
All in One View
Content from Introduction to Data Curation
Last updated on 2026-10-17 | Edit this page
Overview
Questions
- What is data curation, and how does it differ from data management and data cleaning?
- Why does curation matter for research, and for geospatial data in particular?
- What are the stages of the curation lifecycle?
- What do funders and federal policies now expect?
Objectives
- Define data curation and explain its purpose
- Distinguish curation from data management and data cleaning
- Describe the stages of the curation lifecycle
- Explain how public access policies and the FAIR principles shape curation
What is data curation?
Data curation is the work of making data understandable, trustworthy and reusable over the long term, by people who were not involved in creating it. It includes:
- describing data with metadata and documentation
- choosing formats and storage that will last
- depositing data in a repository where it can be found, cited and preserved
- deciding who may access the data and under what license
- protecting sensitive information before data is shared
A museum curator looks after objects so that future visitors can see and understand them. A data curator does the same for datasets.
Curation, management and cleaning
| Data cleaning | Data management | Data curation | |
|---|---|---|---|
| Goal | Correct errors in the data | Keep data organized, safe and usable during a project | Keep data understandable and reusable after the project, by others |
| Typical tasks | Fix typos, duplicates, missing values, invalid geometries | Folders, file names, versions, backups, quality checks | Metadata, documentation, preservation, repositories, licenses, access |
| Time frame | Days to weeks | The life of the project | Years to decades |
| Main audience | The analyst | The project team | Future users, including strangers |
The three overlap, and the Data Management module covers organizing, versioning and quality in detail. This module focuses on what happens so that data can outlive the project that made it.
Curation starts on day one
Curation is often left until a project ends, when the people who understood the data have moved on and the details are forgotten. It is far easier to record where data came from, what each field means and what was done to it while the work happens. Think of curation as a habit, not a final task.
Why curation matters
Poorly curated data leads to:
- Lost data: files on a former student’s laptop, an expired cloud account, an unreadable format
-
Lost meaning: a column called
pct2that nobody can explain, or coordinates with no coordinate system - Irreproducible results: published findings that cannot be checked because the exact data is gone
- Wasted effort: others collecting the same data again because they could not find or trust yours
Well-curated data, by contrast, can be cited (giving its creators credit), verified, combined with other data, and reused for questions its creators never imagined. Census data collected in 1940, carefully preserved, is still used by historians, demographers and geographers today.
Geospatial data adds challenges
- Datasets are often several files (a shapefile) or very large (imagery, lidar)
- They are meaningless without their coordinate reference system
- Boundaries change (census tracts are redrawn every ten years), so the date of the geography matters
- Formats change quickly, and some are proprietary
- Locations can identify people, so sharing needs particular care
The curation lifecycle
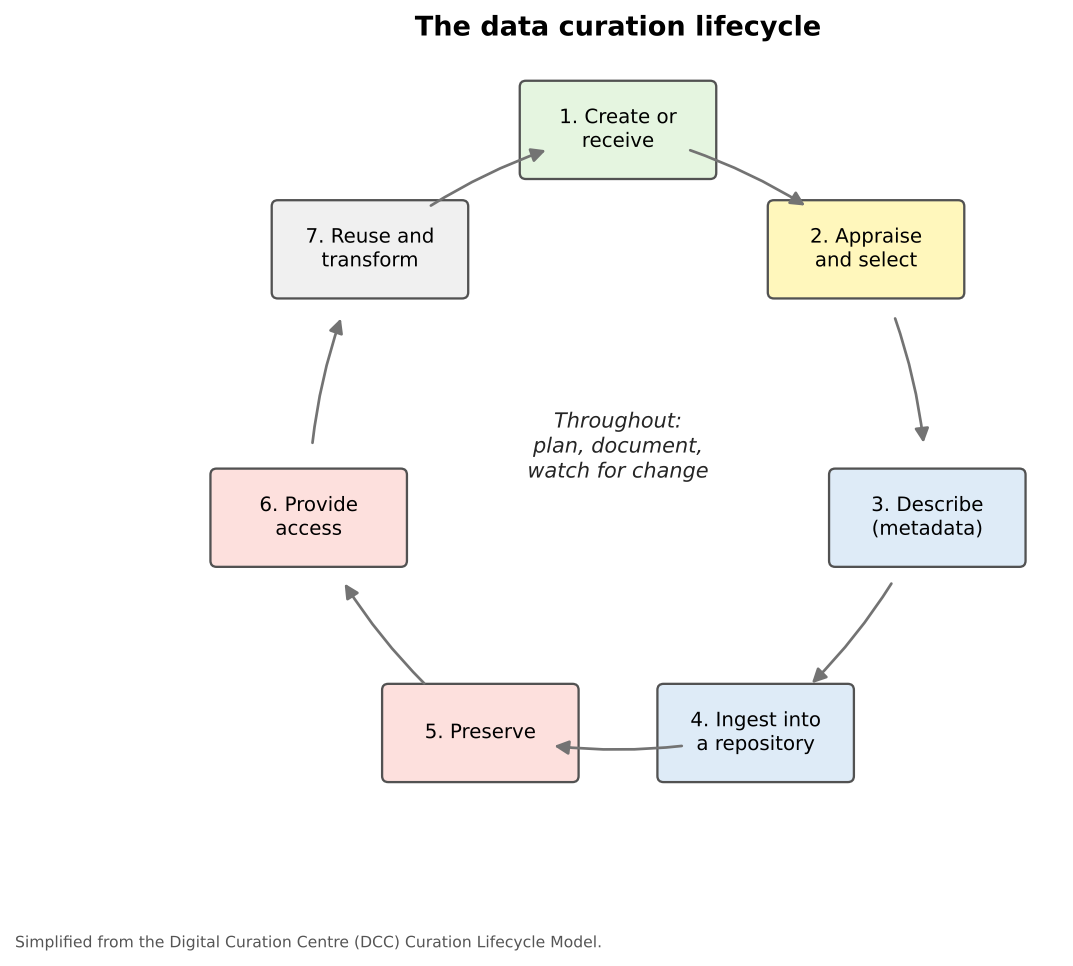
The UK’s Digital Curation Centre (DCC) describes curation as a lifecycle. A simplified version:
| Stage | What happens |
|---|---|
| Create or receive | Data is created by a project, or received from someone else, with its documentation |
| Appraise and select | Decide which data is worth keeping long term, and which can be discarded |
| Describe | Write metadata and documentation so others can find and understand it |
| Ingest | Deposit the data and documentation in a repository or archive |
| Preserve | Keep it safe, readable and unchanged: checksums, backups, format migration |
| Provide access | Make it findable and available, openly or under controlled access |
| Reuse and transform | Others use the data, perhaps creating new datasets that start the cycle again |
Around the whole cycle run planning, documentation, and community watch: keeping an eye on new standards, formats and technologies that may require action.
Appraisal: not everything needs to be kept
Keeping data costs money and effort. A useful set of questions for deciding what to curate:
- Is it the data underlying a publication, or required by a funder or journal?
- Is it unique or hard to recreate (field observations, historical records), or easily downloaded again (a public census table)?
- Is it likely to be useful to others?
- Can it be shared legally and ethically?
For data you downloaded from a stable public source, it is often enough to cite the source precisely (including the version and date) and keep the code that processes it, rather than archiving another copy.
Public access and FAIR
Expectations for sharing research data have grown quickly:
- Funders such as the National Science Foundation and the National Institutes of Health require a data management and sharing plan with proposals.
- A 2022 memorandum from the White House Office of Science and Technology Policy (the “Nelson memo”) directed federal agencies to make publications from federally funded research, and the data underlying them, freely available without delay, and to use persistent identifiers and metadata. Agencies were asked to have updated policies in effect by the end of 2025.
- Many journals ask authors to share data, or to state where it can be found.
Behind these policies are the FAIR principles (published in 2016), which say research data should be:
| Principle | Means | In practice |
|---|---|---|
| Findable | People and computers can discover it | A persistent identifier (DOI), rich metadata, a searchable repository |
| Accessible | It can be retrieved, with clear conditions | Standard web access; metadata stays available even if the data is restricted |
| Interoperable | It works with other data and tools | Open formats, standard vocabularies, EPSG codes, standard identifiers such as GEOIDs |
| Reusable | Others can use it correctly | A clear license, detailed documentation and provenance |
FAIR does not mean “open”: sensitive data can be FAIR with controlled access. The following episodes take each part of curation in turn: metadata, documentation, preservation, sharing, and ethics.
Curation, management or cleaning?
Classify each task:
- Removing 12 duplicate survey responses
- Choosing a folder structure for a team project
- Writing a description of each column for a dataset going into a repository
- Converting a final dataset from a proprietary format to GeoPackage for archiving
- Setting up nightly backups of the project drive
- Cleaning
- Management
- Curation (documentation and metadata)
- Curation (preservation), though choosing open formats is good management too
- Management
The boundaries are fuzzy, and that is fine: what matters is that each task gets done.
Keep or cite?
At the end of a project you have: (a) county boundaries downloaded from the Census Bureau, (b) grocery store locations your team verified in the field, (c) a Python script that joins and analyzes them, and (d) 200 maps exported while exploring the data. What would you curate and deposit, and what would you only cite or discard?
- (a) Cite precisely (product, year, URL, date accessed). It is already preserved by the Census Bureau.
- (b) Curate and deposit: it is unique, and recreating it would mean repeating the field work.
- (c) Deposit with the data: the code documents exactly how results were produced.
- (d) Keep only the maps used in publications; exploratory maps can be regenerated from (a) to (c).
- Data curation makes data understandable, trustworthy and reusable over the long term by people outside the project
- Curation complements data management (during the project) and data cleaning (fixing errors)
- The curation lifecycle runs from creation through appraisal, description, ingest, preservation, access and reuse
- Funders and federal policy increasingly require data underlying publications to be shared
- FAIR data is findable, accessible, interoperable and reusable, which does not always mean open
Content from Metadata
Last updated on 2026-10-17 | Edit this page
Overview
Questions
- What is metadata, and what kinds are there?
- What should a metadata record for a geospatial dataset include?
- Which metadata standards are used for geospatial and social science data?
- How can I create metadata in QGIS?
Objectives
- Define metadata and distinguish descriptive, administrative, structural and technical metadata
- List the essential elements of geospatial metadata
- Recognize the main metadata standards and when each is used
- Write a basic metadata record for a dataset
Data about data
Metadata is structured information that describes a dataset. It answers the questions a stranger would ask before using your data: What is it? Who made it? When and where does it describe? How was it made? How accurate is it? Can I use it, and how do I cite it?
Imagine finding a file called stores.gpkg with 64 points
and no description. Are they grocery stores or hardware stores? Verified
or guessed? From 2015 or 2026? Without metadata, even accurate data is
close to useless, and it cannot be found by searching a catalog.
Kinds of metadata
| Kind | Describes | Examples |
|---|---|---|
| Descriptive | What the data is, so it can be found and understood | Title, abstract, keywords, creator, subject, spatial and temporal coverage |
| Administrative | How it can be managed and used | License and rights, access restrictions, contact, funding, provenance |
| Structural | How it is organized | Files and how they relate, layers in a GeoPackage, tables and keys |
| Technical | How it is encoded | File format, size, coordinate reference system, resolution, software used |
Provenance (or lineage) deserves special mention: the record of where data came from and every process applied to it. It is what allows others to judge quality and reproduce results.
What geospatial metadata should include
| Element | Example for the grocery store dataset |
|---|---|
| Title | Grocery and food stores, Lafayette and West Lafayette, Indiana, 2026 |
| Abstract | What the data contains, why it was created and how it can be used |
| Keywords | food access, grocery stores, SNAP, Indiana, Tippecanoe County |
| Creator and contact | Names, affiliation and an email or ORCID |
| Spatial extent | A bounding box: west -86.97, east -86.77, south 40.35, north 40.50 |
| Temporal extent | The period the data describes: October 2026 |
| Coordinate reference system | EPSG:4326 (WGS 84) |
| Scale or resolution | Positional accuracy about 5 to 10 m |
| Lineage | Downloaded from OpenStreetMap on a stated date; filtered to food stores; cleaned in QGIS; spot-checked in the field |
| Attribute information | Each field, its meaning, type and allowed values (or a link to the data dictionary) |
| Data quality | Completeness, known gaps and how it was checked |
| License and constraints | Open Database License (because it derives from OpenStreetMap) |
| Distribution | Where and in which formats it can be obtained; a DOI if published |
| Metadata date | When the metadata itself was written or updated |
Metadata standards
A metadata standard defines which elements to record, what they are called and how they are encoded, so that catalogs and software can read metadata from many sources.
| Standard | Used for | Notes |
|---|---|---|
| ISO 19115 (19115-1 content, with XML encoding in 19115-3) | Geospatial data worldwide | The main international standard; endorsed by the U.S. Federal Geographic Data Committee (FGDC) in 2016 |
| FGDC CSDGM | U.S. geospatial data, especially older federal data | The former U.S. standard; still widely found, now maintained as a legacy standard while agencies move to ISO |
| ISO 19110 | Feature catalogs | Describes the feature types and attributes of a dataset (a formal data dictionary) |
| Dublin Core | General resources of any kind | Fifteen simple elements (title, creator, date, coverage, rights…); used by many library and repository systems |
| DataCite Metadata Schema | Datasets with DOIs | The metadata registered whenever a DOI is minted; required by repositories such as PURR and Zenodo |
| DDI (Data Documentation Initiative) | Social science surveys and statistical data | Used by ICPSR and many statistical agencies; describes variables, questions and samples in detail |
| STAC (SpatioTemporal Asset Catalog) | Satellite imagery and other geospatial “assets” | A modern JSON-based specification for searchable imagery catalogs |
You rarely write these formats by hand. Repositories ask for metadata through web forms and convert it to standard formats, and GIS software has metadata editors.
Controlled vocabularies
Free-text keywords vary (“food desert”, “food deserts”, “food access”), which makes searching unreliable. Controlled vocabularies provide agreed terms: for example the ISO 19115 topic categories (such as “society”, “health” or “transportation”), the Library of Congress Subject Headings, or place names from GeoNames. Use them where a repository or standard asks for them.
Creating metadata in QGIS
QGIS has a built-in metadata editor based on ISO 19115:
- Right-click a layer and choose Properties, then open the Metadata tab.
- Fill in Identification (title, abstract, type and language), Categories and Keywords, Access (license, rights, constraints), Extent (spatial and temporal), Contact, Links and History (lineage).
- Save it: the metadata can be stored next to the layer as a
.qmdfile or, for a GeoPackage layer, inside the GeoPackage, so it travels with the data.
Projects have metadata too, under Project > Properties > Metadata.
Metadata for downloaded data
When you download data, save its metadata at the same time (most portals offer an XML or PDF file) and note the date, the URL and the version. Sources change: the Census Bureau releases new TIGER/Line files every year, and OpenStreetMap changes every minute.
What is missing?
A dataset in a repository has this metadata:
Title: Bus stops Creator: J. Smith Format: Shapefile Description: Bus stops with amenities.
List at least five important pieces of information that are missing.
- Where: which city or region (a spatial extent)
- When: the date of the data, not just of the upload
- Coordinate reference system
- Lineage: how the stops were mapped (field survey, transit agency data, imagery) and processed
- Attribute information: what the amenity fields mean and their allowed values
- Quality: positional accuracy and completeness
- License and any access constraints
- Contact details, affiliation, and a persistent identifier for citation
- A more specific title: “Bus stops and amenities, Lafayette, Indiana, 2026”
Which standard?
Which metadata standard would you most likely meet in each situation?
- Publishing a dataset with a DOI in Purdue’s repository
- Archiving a national household survey with hundreds of questions
- Describing a statewide land cover layer for a state GIS clearinghouse
- Building a searchable catalog of drone images
- DataCite (the repository’s form produces DataCite metadata for the DOI)
- DDI, used by ICPSR and statistical agencies
- ISO 19115 (or the older FGDC CSDGM, which many state clearinghouses still use)
- STAC
- Metadata is structured information that lets others find, understand, judge and cite a dataset
- Metadata can be descriptive, administrative, structural or technical; provenance records where data came from and what was done to it
- Geospatial metadata must include the spatial and temporal extent, coordinate reference system, resolution or accuracy, lineage and license
- ISO 19115 is the main geospatial standard; DataCite, Dublin Core, DDI and STAC serve other needs
- QGIS has an ISO-based metadata editor; save the metadata with the data
Content from Documentation
Last updated on 2026-10-17 | Edit this page
Overview
Questions
- What documentation should accompany a dataset?
- What goes in a README file?
- How do I document variables, sources and processing steps?
Objectives
- Write a README file for a geospatial dataset
- Document variables in a codebook or data dictionary
- Record provenance: sources, processing steps and software
- Explain how to cite the data you use
Metadata and documentation
Metadata (the previous episode) is structured and short, so that catalogs and search engines can read it. Documentation is the fuller, human-readable explanation that lets someone actually use the data: how it was collected, what every variable means, what was done to it, and what to watch out for.
A well-documented dataset usually has:
| Document | Answers |
|---|---|
| README | What is this, who made it, how is it organized, and how do I use and cite it? |
| Data dictionary or codebook | What does each field mean, in what units, with what allowed values? |
| Methods and provenance notes | How was the data collected and processed, step by step? |
| Code | Exactly how outputs were produced from inputs |
| License | What others may do with it |
The README file
A README is a plain-text file (often
README.md or README.txt) at the top level of a
dataset. It is the first thing anyone opens. Write it as if for a
capable stranger who knows nothing about your project.
A template for a geospatial dataset:
MARKDOWN
# Grocery and Food Stores, Lafayette and West Lafayette, Indiana, 2026

## Overview
Point locations of 64 grocery and food stores, compiled to study food access.
Created by: A. Researcher (Purdue University), ORCID 0000-0000-0000-0000
Contact: a.researcher@example.edu
Date of data: October 2026. Date of this version: 2026-11-01 (version 1.0)

## Files
- grocery_stores.gpkg    the store points (layer: grocery_stores)
- data_dictionary.csv    description of every field
- methods.md             collection and processing steps
- LICENSE.txt            Open Database License (ODbL) 1.0

## Coordinate reference system
EPSG:4326 (WGS 84, latitude and longitude)

## Sources
Store locations: (c) OpenStreetMap contributors, downloaded 2026-10-17 via the Overpass API.
City limits: U.S. Census Bureau, 2024 cartographic boundary files (places).

## Methods (summary)
Food stores were extracted from OpenStreetMap; 12 were verified in the field in
March 2026. See methods.md for details.

## Known limitations
Not all stores were field verified. Small or new stores may be missing.

## How to cite
Researcher, A. (2026). Grocery and Food Stores, Lafayette and West Lafayette,
Indiana, 2026 (Version 1.0) [Data set]. Purdue University Research Repository.
https://doi.org/10.xxxx/xxxxx

## License
Open Database License (ODbL) 1.0, because the data derives from OpenStreetMap.
Keep it current: a README that describes an old version of the data is worse than none.
Codebooks and data dictionaries
A codebook (the usual term for survey data) or data dictionary (the usual term in GIS and databases) describes every variable. For each one, record:
- the name exactly as it appears in the file
- a label or description in plain language
- the type (text, integer, decimal, date)
- units (meters, dollars, percent) and, for money, the year of the dollars
-
allowed values and what each code means
(
1 = Yes,2 = No,9 = Not asked) - how missing values are coded and why they occur
- the source of the variable, especially if it was calculated or came from another dataset
Compare:
| Poor | Better |
|---|---|
pct2: percent |
pct_no_vehicle: Percent of occupied housing units with
no vehicle available. Decimal, 0 to 100. Calculated as B08201_002E /
B08201_001E x 100 from ACS 2020-2024 5-year estimates. Null where the
tract has no households. |
The Designing Your Data episode of the Data Management module shows how to build a data dictionary before collecting data; when you curate the data, that same dictionary becomes part of the documentation.
Provenance: sources and processing
To trust or reproduce a dataset, others need its provenance: every source and every step.
Record your sources precisely
For each input, note:
- the publisher and product name
- the version, vintage or year (for example “TIGER/Line 2024” or “ACS 2020-2024 5-year estimates”)
- the URL or API request
- the date you downloaded it
- its license
Record what you did
Processing steps are easy to forget. Record them as you go:
- Scripts are the best record: they document every step exactly and can be rerun. Comment them, and number them in the order they run.
- For work done by pointing and clicking, keep a processing log: the date, the tool, its settings, and the input and output file names. QGIS also keeps a history of Processing tools you have run (Processing > History), including their parameters.
- Note the software and versions used (for example, QGIS 3.40 or Python 3.12 with geopandas 1.0), because results can change between versions.
Document decisions, not just steps
The most valuable notes record why: why 800 m was chosen as the walking threshold, why two stores were removed, why a particular census year was used. Steps can sometimes be reconstructed from code; reasons cannot.
Citing data
Cite datasets the way you cite articles, so their creators receive credit and readers can find the exact data. A data citation usually includes:
Creator (Year). Title (Version) [Data set]. Publisher. Persistent identifier or URL.
For example:
U.S. Census Bureau. American Community Survey 5-Year Estimates, 2020-2024, Table B08201: Household Size by Vehicles Available [Data set]. Census Data API. Retrieved 2026-10-17 from https://api.census.gov/data/2024/acs/acs5
For data without a DOI, include the access date, since the content behind a URL can change.
Improve the codebook entries
Rewrite each of these as a useful codebook entry:
-
inc: income -
dist: distance to store -
type: 1, 2, 3
-
med_hh_income: Median household income in the past 12 months, in 2024 inflation-adjusted U.S. dollars. Integer. Source: ACS 2020-2024 5-year estimates, variable B19013_001E. Null where the Census Bureau could not calculate an estimate (annotation code -666666666 in the source). -
dist_nearest_supermarket_m: Distance along the road network from the tract’s population-weighted center to the nearest supermarket, in meters. Decimal. Calculated in QGIS with the Shortest path tool on TIGER/Line 2024 roads. -
store_type: Type of store. Text. Allowed values:Supermarket,Small market,Convenience,Other. (Better still, store the words rather than numeric codes; if codes are kept, list what each number means.)
Write a README
Write a short README for a dataset you have created or used (or for the census tract map of households without a car from the Data Collection module). Include at least: a title, creator and contact, the files, the coordinate reference system, sources, a summary of methods, limitations, how to cite it and the license.
Answers will vary. Check your README against these questions:
- Could a stranger tell what the data is and where and when it describes, in under a minute?
- Are all files listed and explained?
- Is the coordinate reference system given as an EPSG code?
- Is every source named, with its version and download date?
- Are known limitations stated?
- Is there a citation and a license?
- Documentation is the human-readable explanation that lets others use data correctly
- Every dataset needs a README covering what, who, when, where, files, CRS, sources, methods, limitations, citation and license
- A codebook or data dictionary describes each variable’s meaning, type, units, values and missing-value codes
- Record provenance: precise sources, every processing step, software versions, and the reasons for decisions
- Cite datasets with creator, year, title, version, publisher and a persistent identifier or URL with access date
Content from Preservation
Last updated on 2026-10-17 | Edit this page
Overview
Questions
- Why does digital data need active preservation?
- Which file formats are safest for the long term?
- How can I tell whether a file has changed or been corrupted?
- What makes a repository trustworthy?
- How are very large datasets stored and moved?
Objectives
- Explain the threats to long-term access to digital data
- Choose preservation-friendly formats for geospatial data
- Explain fixity and checksums
- Describe the OAIS model and the signs of a trustworthy repository
- Recognize the tools and challenges of preserving very large datasets
Digital data does not keep itself
A printed map in a drawer can last centuries. A digital file can become unusable in a few years, without anyone deleting it. The main threats are:
| Threat | Example |
|---|---|
| Media failure | Hard drives, USB sticks and optical discs fail with age, and a single failed drive can hold years of work |
| Bit rot (silent corruption) | A few bits flip during storage or copying, and a file no longer opens or, worse, opens with wrong values |
| Format obsolescence | No current software can read a format any more |
| Loss of context | The file survives but nobody knows what it means (no metadata or documentation) |
| Organizational failure | A lab closes, a student graduates, a cloud account lapses, a website goes offline |
| Human error | Accidental deletion or overwriting |
Digital preservation is the set of activities that keep data accessible, readable, unchanged and understandable for as long as it is needed. Backups (covered in the Data Management module) protect against media failure and human error; preservation also deals with formats, integrity and context over decades.
Preservation-friendly formats
Formats most likely to remain readable are:
- open, with a published specification anyone can implement
- widely used, with many programs that can read them
- well documented and stable over time
- not encrypted or locked to particular software
- lossless, keeping all the original information
The U.S. Library of Congress publishes a Recommended Formats Statement, and many repositories publish their own lists of preferred formats. For geospatial data, good choices are:
| Data | Preferred for preservation | Acceptable, or convert if possible |
|---|---|---|
| Vector | GeoPackage, GeoJSON (for modest sizes), and shapefile (complete with
.prj) |
File geodatabase, KML |
| Raster | GeoTIFF, including Cloud Optimized GeoTIFF; NetCDF for multidimensional data | Proprietary image formats; JPEG (lossy) |
| Tables | CSV (UTF-8 text) | Excel workbooks |
| Documents | PDF/A, plain text, Markdown | Word documents |
| Maps and project files | Export final maps as PDF/A or PNG | QGIS or ArcGIS project files (they depend on software versions and data paths) |
Keep a copy in the original format too, if conversion might lose something, and note the conversion in the documentation.
Fixity: has anything changed?
Fixity means being able to show that a file has not changed since it was stored. It is checked with a checksum (or hash): a short code calculated from the file’s contents, such as a SHA-256 or MD5 value. If even one bit of the file changes, the checksum changes completely.
sha256  3f1a9c...e7b2  grocery_stores.gpkg
sha256  a84d02...19fc  data_dictionary.csv
Repositories calculate checksums when data is deposited and recheck
them regularly, repairing any damaged copy from another. You can do the
same for important files: record checksums in a text file alongside the
data, and compare them after copying or moving data. Free tools exist on
every operating system (for example
certutil -hashfile file SHA256 on Windows, or
shasum -a 256 file on macOS and Linux).
Strategies for keeping data usable
- Multiple copies in different places, regularly checked (fixity), so that a damaged copy can be replaced
- Migration: converting data to a current format before the old one becomes unreadable
- Emulation: running old software on a simulated old computer (mostly used for software and complex digital objects)
- Metadata and documentation: so that the data can still be understood when its creators are gone
- Persistent identifiers (DOIs): so that the data can still be found even if web addresses change
Repositories and the OAIS model
For most researchers, the best preservation strategy is to deposit data in a repository whose job is preservation. Many repositories follow the Open Archival Information System (OAIS) reference model (ISO 14721), which describes an archive in terms of the packages of information it handles:
| Package | What it is |
|---|---|
| Submission Information Package (SIP) | What the depositor provides: data, documentation, metadata |
| Archival Information Package (AIP) | What the archive stores long term, with added preservation metadata and checksums |
| Dissemination Information Package (DIP) | What users receive when they download |
OAIS also stresses that an archive must preserve data for a designated community: the people expected to use it. For social scientists, that means documentation written for researchers who know the field but not your project.
Signs of a trustworthy repository
- It assigns persistent identifiers (DOIs) and keeps the landing page available even if data is withdrawn
- It has a clear preservation policy and commitment (how long, and what happens if it closes)
- It keeps multiple copies and checks fixity
- It requires metadata and reviews deposits
- It holds a certification such as CoreTrustSeal, which assesses repositories against a set of requirements for trustworthiness
Very large datasets
Some datasets, such as satellite image archives, climate model output or national lidar, are far too large for email, USB drives or ordinary cloud folders. Curating them raises new problems:
| Challenge | Approaches |
|---|---|
| Storage cost | Institutional research storage; cloud object storage (such as Amazon S3, Google Cloud Storage or Microsoft Azure); choosing what really needs keeping |
| Moving data | High-speed transfer services such as Globus, used by many universities and computing centers to move terabytes reliably between institutions |
| Using without moving | Cloud-optimized formats (Cloud Optimized GeoTIFF, Zarr, GeoParquet) let users read only the part they need over the web |
| Describing collections | Machine-readable metadata and catalogs, such as STAC for imagery |
| Preservation over decades | Format migration plans, documented processing so that derived products can be regenerated |
A useful question for large data: does it need to be preserved, or can it be recreated? Raw satellite images are preserved by space agencies; a project may only need to preserve its code and the small derived products.
Format choices for an archive
You are depositing a project’s final data. Which formats would you use for each item?
- Census tract polygons joined to ACS estimates, currently in an Esri file geodatabase
- A land cover raster, currently in a proprietary image format
- A survey spreadsheet with several tabs and colored cells marking problems
- The final maps from your thesis, made in QGIS
- GeoPackage (or GeoJSON if small), plus a CSV of the attribute table with GEOIDs as text
- GeoTIFF with lossless compression, with its CRS and NoData value recorded
- One CSV per tab, with the meaning of the colors
turned into an explicit column (for example
flag_reason), and a codebook - PDF/A or high-resolution PNG exports, plus the QGIS project and its data for anyone who wants to remake them (noting the QGIS version)
Why checksums?
A collaborator copies 300 GB of imagery to an external drive and mails it to you. How can you be sure every file arrived intact?
Ask the collaborator to calculate a checksum (such as SHA-256) for every file before sending, and to include the list. After copying the files from the drive, calculate the checksums again and compare. Any file whose checksum differs was corrupted and must be sent again. Transfer services such as Globus check integrity automatically.
- Digital data is threatened by media failure, silent corruption, format obsolescence, loss of context and organizational change
- Preserve data in open, widely used, well-documented, lossless formats such as GeoPackage, GeoTIFF and CSV
- Checksums provide fixity: proof that a file has not changed
- Deposit data in a trustworthy repository that assigns persistent identifiers and has a preservation commitment
- Very large data needs research storage, transfer services such as Globus, and cloud-optimized formats
Content from Sharing and Publishing Data
Last updated on 2026-10-17 | Edit this page
Overview
Questions
- Where should I share my research data?
- What is a DOI, and why does it matter?
- Which license should I choose for my data?
- How do the FAIR and CARE principles guide sharing?
Objectives
- Compare institutional, disciplinary and general-purpose repositories
- Explain persistent identifiers, including DOIs and ORCIDs
- Choose an appropriate license, and respect the licenses of the data you reuse
- Distinguish open, embargoed and controlled access
- Apply the FAIR and CARE principles when sharing data
Why share data?
Sharing data lets others verify your findings, build on your work, and cite it, which gives you credit for the effort of creating it. It is increasingly required: by funders (in data management and sharing plans), by federal public access policies, and by many journals. And it avoids the waste of others collecting the same data again.
Sharing well, however, takes more than emailing a file on request (“data available upon request” often turns out to mean “no longer available”). It means putting the data, with its documentation, somewhere designed to keep it findable and accessible.
Choosing a repository
| Kind | Examples | Good for |
|---|---|---|
| Institutional | Purdue University Research Repository (PURR) | Any data from Purdue researchers; local support from the Libraries |
| Disciplinary (domain) | ICPSR (social and behavioral science), OpenTopography (elevation and lidar), Qualitative Data Repository (qualitative social science) | Reaching the right community; expert curation; standards for the field |
| General-purpose | Zenodo, Harvard Dataverse, Open Science Framework (OSF), figshare, Dryad | Data with no obvious disciplinary home |
| Government portals | Data.gov, state GIS portals | Data produced by or for government agencies |
| Code platforms | GitHub, linked to Zenodo for a DOI | Code and small text-based data, plus documentation |
Ask:
- Does my funder or journal require or recommend a particular repository?
- Is there a disciplinary repository my readers already use?
- Does it assign DOIs, require metadata, and have a preservation commitment?
- Can it handle my data’s size and any need for restricted access?
- Does it cost anything, and how long will it keep the data?
PURR at Purdue
PURR (https://purr.purdue.edu/) is Purdue’s research repository. Researchers create a project space to collaborate and store files (each project starts with 100 GB, and grant-funded projects can be increased to 1 TB at no cost), and can then publish a dataset, which receives a DataCite DOI and is archived for the long term. Collaborators from other institutions can be invited to a project. The Purdue Libraries can help prepare data for publication.
ICPSR for social science
The Inter-university Consortium for Political and Social Research (ICPSR, at the University of Michigan) archives social and behavioral science data, including many major surveys. It curates deposits (checking files, writing codebooks, removing identifying information) and offers restricted-use access for sensitive data, including data with detailed geography.
Persistent identifiers
A web address can break; a persistent identifier (PID) is designed to keep working.
- A DOI (Digital Object Identifier), such as
https://doi.org/10.4231/XXXX, identifies a dataset (or article) and always resolves to its current landing page. Repositories register dataset DOIs, usually through DataCite, along with standard metadata. - An ORCID iD (such as
0000-0002-1825-0097) identifies you as a researcher, so your datasets and papers are linked to you even if your name or institution changes.
The 2022 federal public access memo specifically asks agencies to use persistent identifiers for research outputs and researchers.
Licenses
A license tells others what they may do with your data. Without one, people may be unsure whether they can reuse it at all. Common choices for data:
| License | What it allows | Notes |
|---|---|---|
| CC0 (public domain dedication) | Any use, no conditions | Recommended by many repositories for data; citation is still expected by scholarly norms |
| CC BY 4.0 | Any use, with attribution | A common default; requires credit to the creator |
| ODbL (Open Database License) | Use and share, with attribution, and share-alike for adapted databases | The license of OpenStreetMap; data derived from OSM must keep it |
| CC BY-NC (non-commercial) | Use with attribution, but not commercially | Restrictive and often unclear; generally discouraged for research data |
Some things to know:
- Respect the licenses of what you reuse. If your dataset is built from OpenStreetMap, it must remain under the ODbL with attribution. U.S. federal data (such as Census Bureau data) is generally in the public domain.
- In the United States, facts themselves are not protected by copyright, though the selection and arrangement of a database can be; licenses make your intentions clear either way.
- You can only license what you have the right to share. Data from interviews, purchased data or data under a data use agreement may not be yours to license openly.
Levels of access
Not all data can be fully open. Repositories support several levels:
| Level | What it means | When to use it |
|---|---|---|
| Open | Anyone can download | Most non-sensitive data |
| Embargoed | Metadata public now; data released after a set date | Waiting for a paper to be published or a patent to be filed |
| Controlled (restricted) access | Approved users only, often under a data use agreement or in a secure environment | Sensitive data, such as confidential survey responses or detailed locations of people |
| Metadata only | The record describes the data and how to request it | Data that cannot be deposited, such as licensed commercial data |
Even when data must be restricted, publishing its metadata makes it findable, and is part of being FAIR.
FAIR and CARE
The FAIR principles (findable, accessible, interoperable, reusable), introduced in the first episode, are about making data work well for machines and researchers.
The CARE principles for Indigenous data governance, published by the Global Indigenous Data Alliance in 2019, add a focus on people and purpose, especially for data about Indigenous peoples, lands and resources:
| Principle | Meaning |
|---|---|
| Collective benefit | Data ecosystems should allow Indigenous peoples to benefit from the data |
| Authority to control | Indigenous peoples’ rights and interests in data about them must be recognized, including their authority to govern it |
| Responsibility | Those working with the data must show how it supports self-determination and collective benefit |
| Ethics | The rights and wellbeing of Indigenous peoples should be the primary concern throughout the data lifecycle |
The two are meant to be used together: “Be FAIR and CARE.” Geospatial data about sacred sites, land use or resources can have serious consequences for communities, so it should be shared only in ways the communities concerned agree to.
Pick a repository
Where would you deposit each dataset, and why?
- Anonymized responses from a national survey about housing, with county of residence
- Grocery store points you verified in the field in Lafayette, Indiana, for a Purdue thesis
- A 2 TB lidar point cloud of a river corridor
- The Python code and small GeoJSON files behind a published paper
- ICPSR: the social science community uses it, and it can offer restricted access if county plus other answers could identify people.
- PURR: Purdue’s repository, with a DOI and local support (Zenodo or Harvard Dataverse would also work).
- OpenTopography (a disciplinary repository for elevation data), or institutional research storage for the raw data plus a repository record with a DOI.
- GitHub for development, archived to Zenodo (or PURR) for a DOI that matches the published version.
Pick a license
Which license would suit each case?
- Tract-level statistics you calculated from public Census Bureau data
- A layer you created by editing and adding to OpenStreetMap data
- Interview transcripts collected under consent forms that promised confidentiality
- CC0 or CC BY 4.0: the inputs are public domain, so you are free to choose an open license.
- ODbL: it is a derivative of OpenStreetMap, so it must be shared under the same license with attribution.
- No open license: the consent forms rule out public sharing. Share only de-identified data (if the consent allows), under controlled access with a data use agreement, or share metadata only.
- Share data through a repository rather than on request; choose disciplinary, institutional or general-purpose repositories to suit the data
- PURR is Purdue’s repository; ICPSR is the main archive for social science data
- Persistent identifiers (DOIs for data, ORCID iDs for people) keep data findable and creators credited
- Choose a clear license (often CC0 or CC BY), and keep the licenses of data you reuse, such as ODbL for OpenStreetMap
- Data can be open, embargoed, controlled or metadata-only; apply both FAIR and CARE principles
Content from Ethics and Sensitive Location Data
Last updated on 2026-10-17 | Edit this page
Overview
Questions
- Why can location data identify people, even without names?
- How can geospatial data be shared while protecting privacy?
- What other kinds of location data are sensitive?
- What ethical and legal obligations apply?
Objectives
- Explain how locations and small counts can re-identify people
- Describe aggregation, geomasking, coordinate coarsening and suppression, and their trade-offs
- Recognize sensitive locations beyond personal data, such as archaeological sites and places important to communities
- Plan consent, review and access controls for sensitive geospatial data
Location is personal
Removing names from a dataset does not make it anonymous if it contains locations. A home address, or a point on a map that falls on one house, identifies a household as surely as a name. Combined with a few other details (age, sex, the date of a visit), even approximate locations can single people out.
- In a widely cited study of mobile phone records for 1.5 million people, four points in space and time were enough to uniquely identify 95% of individuals (de Montjoye and colleagues, Scientific Reports, 2013).
- Maps of individual cases (illnesses, crimes, survey responses) have been used to find the people behind them.
- Small areas can reveal individuals through small counts: if a census block contains one household of a particular kind, a table for that block describes that household.
This is why the U.S. Census Bureau applies disclosure avoidance to everything it publishes. For the 2020 Census it adopted a method based on differential privacy, which adds carefully calibrated noise to published counts, especially for small areas.
Sensitive does not only mean personal
Some locations need protection even when no person is identified:
- Archaeological sites: published locations invite looting. U.S. federal law (including the Archaeological Resources Protection Act) allows agencies to withhold site locations.
- Sacred and culturally significant places: their location may be knowledge that a community does not wish to share (see the CARE principles in the previous episode).
- Endangered species: nest, den or plant locations can attract poachers or collectors.
- Critical infrastructure and shelters (for example, for survivors of domestic violence).
Methods for protecting locations
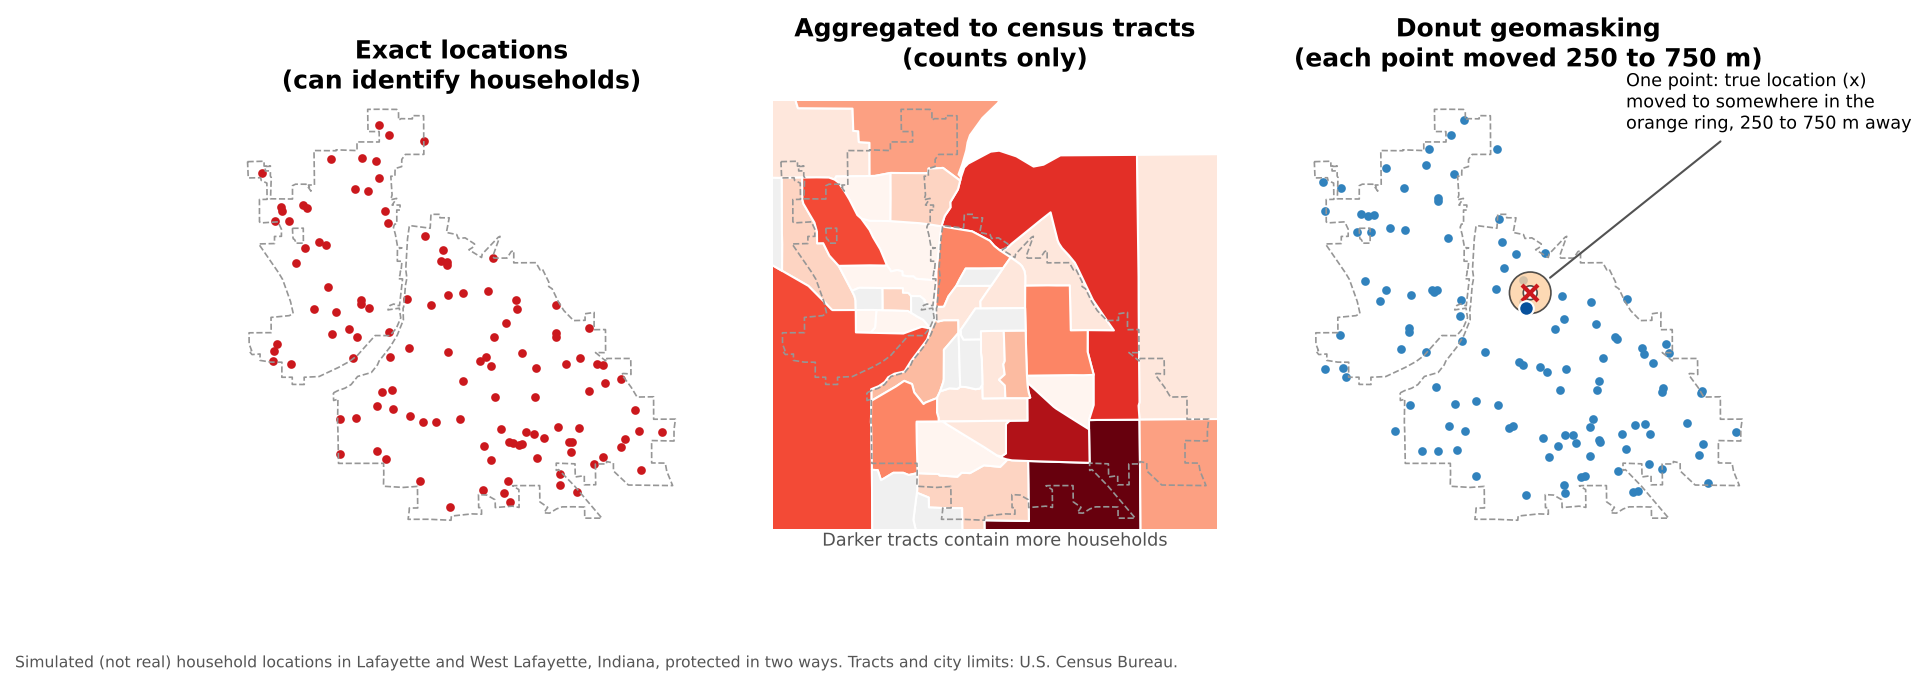
There is always a trade-off between protection and usefulness: the more a location is changed or hidden, the safer it is, and the less precise the analysis it supports.
| Method | What it does | Strengths | Weaknesses |
|---|---|---|---|
| Aggregation | Report counts or rates for areas (tracts, ZIP codes, grid cells) instead of points | Simple, familiar, works with census data | Loses detail; results depend on the areas chosen; small areas can still disclose |
| Geomasking (random perturbation) | Move each point a random distance and direction | Keeps point patterns approximately | Points can land in implausible places (rivers, other towns); too small a move protects little |
| Donut geomasking | Move each point at least a minimum and at most a maximum distance | Guarantees every point moves; good balance for health and survey data | Needs care in sparsely populated areas, where a 500 m move may not hide anyone |
| Coordinate coarsening | Round coordinates to fewer decimal places | Very simple | Creates a visible grid; protection depends on population density |
| Suppression | Withhold counts below a threshold (for example, fewer than 10) | Standard for published tables | Information is lost; suppressed cells can sometimes be recalculated from totals |
| Controlled access | Keep precise data, but share it only with approved users in a secure setting | Full precision for legitimate research | Slower and more limited access |
How much does rounding coordinates hide? At the latitude of Indiana:
| Decimal places (degrees) | Approximate precision |
|---|---|
| 2 (40.42) | about 1 km |
| 3 (40.425) | about 100 m: a city block |
| 4 (40.4247) | about 10 m: a single building |
| 5 or more | about 1 m or better: a specific spot |
Most phone GPS coordinates are recorded with six or more decimal places, far more precise than needed for most social science analysis, and far more revealing.
Health data rules give a useful benchmark
Under the U.S. HIPAA “Safe Harbor” rule for de-identifying health information, geographic units smaller than a state, such as street addresses, cities, counties and full ZIP codes, must be removed. The first three digits of a ZIP code may be kept only if that three-digit area contains more than 20,000 people. Your project may not be covered by HIPAA, but the rule shows how seriously small-area geography is treated.
Consent, review and agreements
- Institutional review. Research that collects information about identifiable people usually requires review by an Institutional Review Board (IRB) before data collection starts. Describe in the protocol what location data you will collect, how precise it will be, and how it will be protected and shared.
- Informed consent. Tell participants what will be shared, with whom, and in what form. If the consent form promises that locations will never be released, they cannot later be published, even in a repository.
- Data use agreements. Data obtained from others (health departments, companies, other researchers) often comes with rules on storage, linking and publication. Follow them, and record them in your documentation.
- Secure storage. Keep identifiable data only in approved, access-controlled storage, separate from de-identified working files, and delete it when it is no longer needed and the agreement allows.
Beyond privacy: the power of maps
Maps shape decisions about investment, policing, insurance and services. Ethical practice also means asking:
- Who could be harmed if this map or dataset were misused?
- Does labeling an area (a “food desert”, a “high-crime neighborhood”) stigmatize the people who live there?
- Were the communities being mapped involved, and do they benefit?
- Does the data represent everyone, or are some groups missing (people without phones, without addresses, or not counted)?
A checklist before sharing location data
- Does the dataset contain locations of people, or of sensitive places?
- What did consent forms, the IRB approval and any data use agreements permit?
- Could someone re-identify a person by combining the locations with other columns or with public data?
- Is the precision greater than the analysis needs? Can it be aggregated, masked or rounded?
- Are there small counts that should be suppressed?
- Should the data be open, controlled access, or metadata only?
- Is the protection method documented, so users understand the limitations it introduces?
The home coordinates identify each household almost exactly, and combined with age and sex they would identify most respondents. Options include:
- Remove the coordinates and share the census tract (or block group) GEOID instead, after checking that no tract has only a handful of respondents with the same age and sex.
- Or apply donut geomasking with a distance suited to the population density, and coarsen age into groups.
- Share the precise data, if at all, only through controlled access (for example at ICPSR), as the consent form allows.
- Document the protection method so users know the locations are approximate.
Choose the masking distance
You are geomasking survey locations in two places: downtown Lafayette, where thousands of people live within a few hundred meters, and a rural part of the county with a few farmhouses per square kilometer. Should you use the same masking distance in both? Why or why not?
No. What protects people is the number of other households a masked point could plausibly belong to, not the distance itself. A move of a few hundred meters hides a household among hundreds of others downtown, but in the countryside it may still point to a single farm. Use larger distances where population density is low (or adaptive methods that scale the distance to the local population), or aggregate rural responses to larger areas.
- Locations can identify people even without names, especially combined with other attributes or small counts
- Aggregation, geomasking, coordinate coarsening, suppression and controlled access protect locations, each with a trade-off in precision
- Some places need protection even when no person is involved: archaeological sites, sacred places, endangered species
- Plan protection before collecting data: IRB review, informed consent, data use agreements and secure storage
- Document how locations were protected, and consider who could be harmed by a map